Showing posts with label T-SQL. Show all posts

Tuesday, March 17, 2026

How to use Dynamic SQL to Consolidate Data from multiple Tables with different Structures

How to use Cursor in SQL to Consolidate Data from various Tables with different Structures
Scenario:
Suppose you are working in a pharmaceutical company where information is distributed across several systems. Each system captures different attributes:
  • Clinical trials record patient groups, their clinical responses, and efficiency rates.
  • Production records track manufacturing details such as batch yield ratios and batch quantities.
  • Sales transactions capture commercial data like regions, customer types, and sales amounts.
While this design works well for transactional systems, it becomes difficult when you need to analyze or report across all of them in a consistent way.
For example, management may want to see how a drug performed in trials, how efficiently it was produced, and how much revenue it generated, in a consolidated view.

The challenge is to create a Unified_Data_Repository that standardizes data from these diverse sources. Instead of wide tables with many columns, the goal is to reshape the data into a normalized tall format. 

In this structure, each column value is transformed into a row, making it easier to query, compare, and report across the various heterogeneous tables.

The consolidated Output table follows a simple schema as per below:
  • ID: represents the original row identifier from the source table.
  • Criteria_Name: the name of the column being transformed.
  • Criteria_Value: the actual value from that column, stored as text.
  • Src_Object_Name: the source table name, ensuring traceability.
  • _LastModified_On: a timestamp marking when the record was inserted.
We can achieve this Scenario using Dynamic SQL with Cursor as explained below:
-----------------------------------------------------------------
Step1: Create Sample Input Source Tables:
-----------------------------------------------------------------
-- Sample of Clinical trial data
CREATE TABLE [dbo].[Clinical_Trials] 
(
    Trial_ID INT,
    Drug_Code VARCHAR(50),
    Patient_Group VARCHAR(50),
    Clinical_Response VARCHAR(100),
    Efficiency_Rate DECIMAL(10,2)
);

INSERT INTO [dbo].[Clinical_Trials] VALUES
(1001, 'Drug_A01', 'Adults', 'Positive', 87.5),
(1002, 'Drug_B02', 'Children', 'Neutral', 65.0),
(1003, 'Drug_C03', 'Elderly', 'Negative', 42.3);

SELECT * FROM [dbo].[Clinical_Trials]


-- Sample of Production records
CREATE TABLE [dbo].[Production_Records] 
(
    Batch_ID INT,
    Drug_Code VARCHAR(50),
    Plant_ID VARCHAR(50),
    Batch_Yield_Ratio DECIMAL(10,2),
    Batch_Quantity DECIMAL(10,2)
);

INSERT INTO [dbo].[Production_Records] VALUES
(2001, 'Drug_A01', 'Plant_001', 95.2, 1200.5),
(2002, 'Drug_B02', 'Plant_002', 89.7, 980.0),
(2003, 'Drug_C03', 'Plant_003', 76.4, 750.2);

SELECT * FROM [dbo].[Production_Records]


-- Sample of Sales transactions
CREATE TABLE [dbo].[Sales_Transactions] 
(
    Sale_ID INT,
    Region VARCHAR(50),
    Drug_Code VARCHAR(50),
    Customer_Type VARCHAR(50),
    Sales_Amount DECIMAL(10,2)
);

INSERT INTO [dbo].[Sales_Transactions] VALUES
(3001, 'North America', 'Drug_A01', 'Hospital', 15000.0),
(3002, 'Europe', 'Drug_B02', 'Pharmacy', 12000.5),
(3003, 'Asia', 'Drug_C03', 'Distributor', 9800.0);

SELECT * FROM [dbo].[Sales_Transactions]

-----------------------------------------------------------------
Step 2: Create the Unified Output Table to store final Output Data:
-----------------------------------------------------------------
CREATE TABLE [dbo].[Unified_Data_Repository] 
(
    ID INT,
    Criteria_Name VARCHAR(200),
    Criteria_Value VARCHAR(200),
    Src_Object_Name VARCHAR(200),
    _LastModified_On DATETIME
);

-----------------------------------------------------------------
Step 3: Create a Temp Table with Source Table Names and Key Columns:
-----------------------------------------------------------------
IF OBJECT_ID('tempdb..##Src_Table_Mapping') IS NOT NULL 
DROP TABLE ##Src_Table_Mapping;

CREATE TABLE ##Src_Table_Mapping (
    Source_Table VARCHAR(128),
    Key_Column  VARCHAR(128)
);

INSERT INTO ##Src_Table_Mapping VALUES
('Clinical_Trials', 'Trial_ID'),
('Production_Records', 'Batch_ID'),
('Sales_Transactions', 'Sale_ID');

SELECT * FROM ##Src_Table_Mapping;

-----------------------------------------------------------------
Step 4: Dynamic SQL Query with Cursor to consolidate Data from all Source tables
-----------------------------------------------------------------
-- Declare variables to hold table name and SQL statement
DECLARE @TableName NVARCHAR(200);
DECLARE @sql NVARCHAR(MAX);
DECLARE @KeyColumn NVARCHAR(200);

-- Define a Cursor that will loop through all Source table names
DECLARE _CursorX Cursor FOR
SELECT Source_Table, Key_Column FROM ##Src_Table_Mapping;

-- Open the Cursor (initializes the result set)
OPEN _CursorX;

-- Fetch the first record (first table name from mapping)
FETCH NEXT FROM _CursorX INTO @TableName, @KeyColumn;

-- Loop until all records are processed
WHILE @@FETCH_STATUS = 0
BEGIN
    SET @sql = '';

    -- Build dynamic SQL for the _CursorXrent table
    -- This Pivots columns into rows and inserts them into Unified_Data_Repository
    SELECT @sql = 
        'INSERT INTO [dbo].[Unified_Data_Repository] 
        (ID, Criteria_Name, Criteria_Value, Src_Object_Name, _LastModified_On) ' +
        (
        SELECT STRING_AGG(
            'SELECT ' + @KeyColumn + ' AS ID, ''' + COLUMN_NAME + ''' AS Criteria_Name, ' +
            'CAST(' + COLUMN_NAME + ' AS NVARCHAR(200)) AS Criteria_Value, ' +
            '''' + @TableName + ''' AS Src_Object_Name, GETDATE() AS _LastModified_On ' +
            'FROM [dbo].[' + @TableName + ']',
            ' UNION ALL '
            )
        FROM INFORMATION_SCHEMA.COLUMNS
        WHERE TABLE_NAME = @TableName
        AND COLUMN_NAME <> @KeyColumn  -- Exclude Key column from Pivot
        );

    -- Execute the dynamic SQL for this table
    EXEC(@sql);

    -- Fetch the next record (next table name)
    FETCH NEXT FROM _CursorX INTO @TableName, @KeyColumn;
END

-- Close the Cursor (release resources)
CLOSE _CursorX;

-- Deallocate the Cursor (remove definition)
DEALLOCATE _CursorX;
-----------------------------------------------------------------
 Step 5: View the final consolidated Output
-----------------------------------------------------------------
SELECT * 
FROM [dbo].[Unified_Data_Repository]
ORDER BY Src_Object_Name, ID;

-----------------------------------------------------------------
Data Analysis and Insights:
-----------------------------------------------------------------
We can use the consolidated unified dataset to analyze and study the relationship between clinical outcomes and commercial performance. 
By pivoting attributes such as Drug_Code, Efficiency_Rate, and Sales_Amount, the dataset can be transformed into an analytical view that highlights how scientific effectiveness connects with market adoption.
The example below demonstrates how a focused query can turn the normalized repository into actionable insights:

WITH Drug_Data AS (
    SELECT Src_Object_Name, Criteria_Name, Criteria_Value, ID
    FROM Unified_Data_Repository
    WHERE Criteria_Name IN ('Drug_Code','Efficiency_Rate','Sales_Amount')
)
SELECT t1.Criteria_Value AS Drug_Code,
       MAX(CASE WHEN t2.Criteria_Name = 'Efficiency_Rate' THEN t2.Criteria_Value END) AS Efficiency_Rate,
       MAX(CASE WHEN t2.Criteria_Name = 'Sales_Amount' THEN t2.Criteria_Value END) AS Sales_Amount
FROM Drug_Data t1
INNER JOIN Drug_Data t2 ON t1.ID = t2.ID
WHERE t1.Criteria_Name = 'Drug_Code'
GROUP BY t1.Criteria_Value;


Insights Derived from Analysis:
By using the consolidated dataset and pivoting attributes like Drug_Code, Efficiency_Rate, and Sales_Amount, we can understand how clinical effectiveness relates to the performance of the sales. From this analysis, we can derive the following key insights.

1) Clinical vs. Commercial Performance:
  • Drug_A01 shows the highest efficiency rate (87.5%) and the strongest sales (15,000). This indicates strong clinical success translating into strong market adoption.
  • Drug_C03 has the lowest efficiency (42.3%) and the weakest sales (9,800), suggesting limited clinical effectiveness is reflected in lower demand.
2) Correlation Between Metrics:
  • Drug_A01 shows a positive correlation: higher efficiency rates tend to align with higher sales amounts.
  • Drug_B02, with moderate efficiency (65%) but relatively strong sales (12,000.5), shows that commercial performance can sometimes outpace clinical effectiveness, possibly due to market factors like pricing, distribution, or brand strength.
3) Strategic Decision Support:
  • Drug_B02 may need further clinical improvement to match its commercial success, ensuring long‑term sustainability and patient satisfaction.
  • Drug_C03 could require both clinical enhancements and stronger commercial strategies to improve its overall performance.
Note:
This article shows how Dynamic SQL with Cursors can be used to consolidate data. The examples are for learning purposes, and you can refine and adapt the logic to fit your own requirements.
--------------------------------------------------------------------------------------------------------
Thanks, TAMATAM ; Business Intelligence & Analytics Professional
--------------------------------------------------------------------------------------------------------

Saturday, March 7, 2026

How to Apply Permutations and Combinations Logic in SQL to Analyze Transaction Data

How to Use SQL Window Functions to Analyze Transactional Data with Permutations and Combinations
Scenario:
Suppose you are working with a financial system that processes millions of transactions every day. To detect anomalies, understand customer behavior, or ensure compliance, analysts often need to examine both the relationships between transactions (combinations) and the order in which transactions occur (permutations).

Statistical Concepts:
In probability theory, permutations and combinations are methods of counting the possible outcomes.
N = Total number of elements in the sample space (here, number of transactions).
r = Number of elements selected at a time (e.g., pairs of transactions).

Combinations: Choosing r elements from N, where order does not matter.

(Nr)=N!r!(Nr)!

Example: Choosing r=2 transactions from N=5 results in (52)=10 possible pairs. In combinations, (A,B) is considered the same as (B,A), so duplicates are ignored.

Permutations: Choosing r elements from N, where order matters.

P(N,r)=N!(Nr)!

Example: Choosing r=2 transactions from N=5 results in P(5,2)=20 possible sequences. In permutations, (A,B) is different from (B,A), so both orders are considered.

In this article, we will use a simple scenario with sample data to show how permutations and combinations, and running balances can be applied in SQL to uncover useful insights.

Sample Table: tbl_Sample_Transactions

CREATE TABLE tbl_Sample_Transactions (
    TransactionID INT,
    AccountID VARCHAR(10),
    TransactionDate DATE,
    Amount DECIMAL(10,2),
    Type VARCHAR(20)
);

INSERT INTO tbl_Sample_Transactions VALUES
(1, 'A001', '2024-01-01', 500, 'Deposit'),
(2, 'A001', '2024-01-02', -200, 'Withdrawal'),
(3, 'A001', '2024-01-03', -100, 'Transfer'),
(4, 'A002', '2024-01-01', 1000, 'Deposit'),
(5, 'A002', '2024-01-04', -300, 'Withdrawal'),
(6, 'A002', '2024-01-05', -200, 'Transfer'),
(7, 'A003', '2024-01-02', 700, 'Deposit'),
(8, 'A003', '2024-01-03', -400, 'Withdrawal'),
(9, 'A003', '2024-01-06', -100, 'Transfer'),
(10,'A003', '2024-01-07', 300, 'Deposit');

SELECT * FROM tbl_Sample_Transactions


1) Combinations: Transaction Pairs (Order Doesn’t Matter)
Combinations are useful when we want to study pairs of transactions that occur together, regardless of order. For financial analysis, this helps detect linked activities such as deposit–withdrawal pairs or withdrawal–transfer pairs.

Here, in this query we consider combinations of r=2 transactions from N. We avoid duplicates by considering only one side (Txn1, Txn2) and ignoring the flipside.

-- Combinations (N, r=2)
SELECT 
    t_left.AccountID,
    t_left.TransactionID AS Txn1,
    t_left.Type AS Txn1Type,
    t_right.TransactionID AS Txn2,
    t_right.Type AS Txn2Type
FROM (
    SELECT *,
           ROW_NUMBER() OVER (PARTITION BY AccountID ORDER BY TransactionID) AS rn
    FROM tbl_Sample_Transactions
) t_left
INNER JOIN (
    SELECT *,
           ROW_NUMBER() OVER (PARTITION BY AccountID ORDER BY TransactionID) AS rn
    FROM tbl_Sample_Transactions
) t_right
ON t_left.AccountID = t_right.AccountID AND t_left.rn < t_right.rn
WHERE t_left.AccountID = 'A003'   -- Filter the Account A003 for Analysis
ORDER BY t_left.AccountID, Txn1, Txn2;

-- We can also re-write the above query using CTE as per below:

WITH Ranked_Transactions AS (
    SELECT 
        AccountID,
        TransactionID,
        Type,
        ROW_NUMBER() OVER (PARTITION BY AccountID ORDER BY TransactionID) AS rn
    FROM tbl_Sample_Transactions
    WHERE AccountID = 'A003'   -- Filter the Account A003 for Analysis
    )
SELECT 
    t1.AccountID,
    t1.TransactionID AS Txn1,
    t1.Type AS Txn1Type,
    t2.TransactionID AS Txn2,
    t2.Type AS Txn2Type
FROM Ranked_Transactions t1
INNER JOIN Ranked_Transactions t2
  ON t1.rn < t2.rn
ORDER BY t1.AccountID, Txn1, Txn2;

Result:

Financial Insights from Combinations:

  • A Deposit paired with a Withdrawal (Txn7 and Txn8) highlights immediate cash-out after funding. Fraud detection teams often flag this as potential cash recycling, where funds are deposited and withdrawn quickly to disguise their origin.
  • A Withdrawal paired with a Transfer (Txn8 and Txn9) suggests funds are being moved across accounts after withdrawal. This is a classic layering technique in money laundering, where money is shuffled to obscure its trail.
  • A Deposit paired with another Deposit (Txn7 and Txn10) indicates repeated funding activity. Analysts use this to study liquidity behavior, customer saving patterns, and potential inflows from multiple sources.
2) Permutations: Transaction Sequences (Order Matters)
Permutations are useful when we want to study the order of transactions. In financial terms, this helps us analyze transaction flows — the exact sequence in which deposits, withdrawals, and transfers occur.

Here, in this query we consider the permutations of r=2 transactions from N, considering both directions (Txn1 → Txn2 and Txn2 → Txn1).

-- Permutations (N, r=2)
SELECT 
    t_left.AccountID,
    t_left.TransactionID AS Txn1,
    t_left.Type AS Txn1Type,
    t_right.TransactionID AS Txn2,
    t_right.Type AS Txn2Type
FROM (
    SELECT *,
           ROW_NUMBER() OVER (PARTITION BY AccountID ORDER BY TransactionID) AS rn
    FROM tbl_Sample_Transactions
) t_left
INNER JOIN (
    SELECT *,
           ROW_NUMBER() OVER (PARTITION BY AccountID ORDER BY TransactionID) AS rn
    FROM tbl_Sample_Transactions
) t_right
ON t_left.AccountID = t_right.AccountID AND t_left.rn <> t_right.rn
WHERE t_left.AccountID = 'A003'   -- Filter the Account A003 for Analysis
ORDER BY t_left.AccountID, Txn1, Txn2;

-- We can also re-write the above query using CTE as per below:

WITH Ranked_Transactions AS (
    SELECT 
        AccountID,
        TransactionID,
        Type,
        ROW_NUMBER() OVER (PARTITION BY AccountID ORDER BY TransactionID) AS rn
    FROM tbl_Sample_Transactions
    WHERE AccountID = 'A003'   -- Filter the Account A003 for Analysis
    )
SELECT 
    t1.AccountID,
    t1.TransactionID AS Txn1,
    t1.Type AS Txn1Type,
    t2.TransactionID AS Txn2,
    t2.Type AS Txn2Type
FROM Ranked_Transactions t1
INNER JOIN Ranked_Transactions t2
  ON t1.AccountID = t2.AccountID
 AND t1.rn <> t2.rn
ORDER BY t1.AccountID, t1.TransactionID, t2.TransactionID;

Result:

Financial Insights from Permutations:

  • A Deposit followed by a Withdrawal (Txn7 → Txn8) shows immediate cash-out after deposit. This sequence is a strong indicator of suspicious activity, often linked to fraud or money laundering.
  • A Withdrawal followed by a Deposit (Txn8 → Txn7) reflects replenishment after overdraft. This sequence provides insights into customer liquidity management and spending behavior.
  • A Transfer followed by a Deposit (Txn9 → Txn10) highlights funds being moved and then topped up. Analysts interpret this as either legitimate fund management or potential layering in money laundering schemes.
3) Running Balance Analysis:
Running balances are a way to track how account funds evolve over time. This is essentially a permutation analysis extended across the entire sequence of transactions.
Instead of viewing each transaction separately, we calculate the cumulative impact of all the transactions in sequence. 
This approach provides a continuous picture of how deposits, withdrawals, and transfers affect the account balance at every step in time.

-- Running Balance calculation for all Accounts
SELECT 
    AccountID,
    TransactionID,
    TransactionDate,
    Amount,
    SUM(Amount) OVER ( PARTITION BY AccountID ORDER BY TransactionDate
        ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
    ) AS Running_Balance
FROM tbl_Sample_Transactions
ORDER BY AccountID, TransactionDate;

Result:

Financial Insights from Running Balance:
  • The account starts with a deposit of 500, then decreases to 300 after a withdrawal, and further reduces to 200 after a transfer.
  • Running balances make it easy to spot accounts that are trending downward and may risk overdraft.
  • Compliance teams can monitor whether balances stay above required minimums.
  • Customer behavior can be analyzed more easily: steady deposits indicate saving habits, while frequent withdrawals or transfers highlight spending or fund movement patterns.
  • Risk managers can use these balances to forecast liquidity needs and detect unusual depletion trends across accounts.
Note / Disclaimer:
Examples in this article are for illustration only. Real-world financial systems involve added complexities such as multi-currency, regulatory rules, and fraud detection. Always validate queries and logic against your organization’s compliance and data governance requirements.

--------------------------------------------------------------------------------------------------------
Thanks, TAMATAM ; Business Intelligence & Analytics Professional
--------------------------------------------------------------------------------------------------------

Wednesday, February 5, 2025

How to calculate Monthly and Quarterly Sales Growth in SQL Server

How to calculate Monthly and Quarterly Sales Growth using LAG Function in SQL Server
Scenario:
Suppose we have a Sample table with Sales by Year, Quarter and Month as follows:
/* Check and Drop the Table if already exists */
IF OBJECT_ID('dbo.tbl_Sales_Sample', 'U') IS NOT NULL
BEGIN
    DROP TABLE dbo.tbl_Sales_Sample;
END;

/* Create the sample Sales Table */
CREATE TABLE dbo.tbl_Sales_Sample (
Sales_Year INT,
Qtr_No VARCHAR(2),
        Month_No INT, 
        Total_Sales DECIMAL(10, 2)
);

/* Insert Sample Data */
INSERT INTO dbo.tbl_Sales_Sample (Sales_Year, Qtr_No, Month_No, Total_Sales) 
VALUES
(2021,'Q1', 1, 1000.00),
(2021,'Q1', 2, 1100.00),
(2021,'Q1', 3, 1200.00),
(2021,'Q2', 4, 1300.00),
(2021,'Q2', 5, 1250.00),
(2021,'Q2', 6, 1350.00),
(2021,'Q3', 7, 1400.00),
(2021,'Q3', 8, 1450.00),
(2021,'Q3', 9, 1500.00),
(2021,'Q4', 10, 1600.00),
(2021,'Q4', 11, 1550.00),
(2021,'Q4', 12, 1650.00),
(2022,'Q1', 1, 1700.00),
(2022,'Q1', 2, 1750.00),
(2022,'Q1', 3, 1800.00);
GO

SELECT * FROM dbo.tbl_Sales_Sample;
GO

Based on the above sample data, we will calculate the Monthly and Quarterly Sales Growth using the LAG () Function within CTEs as per below:

/* CTE for Monthly Sales Growth */
;WITH CTE_Monthly_Sales AS (
    SELECT 
        Sales_Year,
Qtr_No,
Month_No,
        SUM(Total_Sales) AS Total_Sales,
        LAG(SUM(Total_Sales)) OVER (ORDER BY Sales_Year, Month_No) AS Prev_Month_Sales
    FROM dbo.tbl_Sales_Sample
GROUP BY Sales_Year,Qtr_No,Month_No
)

SELECT 
    Sales_Year,
Qtr_No,
Month_No,
    Total_Sales,
    Prev_Month_Sales,
    CASE 
        WHEN Prev_Month_Sales IS NOT NULL 
THEN ((Total_Sales - Prev_Month_Sales) / Prev_Month_Sales * 100.0)
        ELSE NULL
    END AS Monthly_Sales_Growth
FROM CTE_Monthly_Sales;
GO

Result:


/* CTE for Quarterly Sales Growth */
;WITH CTE_Qtrly_Sales AS (
    SELECT 
        Sales_Year,
        Qtr_No,
        SUM(Total_Sales) AS Qtrly_Sales,
LAG(SUM(Total_Sales)) OVER (ORDER BY Sales_Year, Qtr_No) AS Prev_Qtr_Sales
    FROM dbo.tbl_Sales_Sample
    GROUP BY Sales_Year, Qtr_No
)

SELECT 
    Sales_Year,
    Qtr_No,
    Qtrly_Sales,
    Prev_Qtr_Sales,
    CASE 
        WHEN Prev_Qtr_Sales IS NOT NULL 
THEN ((Qtrly_Sales - Prev_Qtr_Sales) / Prev_Qtr_Sales * 100.0)
        ELSE NULL
    END AS Qtrly_Sales_Growth
FROM CTE_Qtrly_Sales;

Result:

--------------------------------------------------------------------------------------------------------
Thanks, TAMATAM ; Business Intelligence & Analytics Professional
--------------------------------------------------------------------------------------------------------

Friday, January 26, 2024

How to create Parent and Child Hierarchy using Recursive CTE in SQL Server

How to create Root Node and Leaf Node Hierarchy using Recursive CTE in SQL Server
Scenario 1:
Suppose we have a sample data with ParentNode and ChildNode columns as follows.


Lets say:
A1 is the Parent Node for the Child Node B1. This Child Node can be RootNode or a Parent Node for other Child Nodes as per below.
B1 is the Parent Node for {C1, D1}.
C1 is the Parent Node for {E1, F1}.

Please note that, the A1 is the Root Node which do not have the Parent Node assigned.
Based on this sample, we have to create a [NodeLevelsPath] column with values as per below:
The Node Hierarchy for A1 = A1
The Node Hierarchy for C1 = A1|B1|C1
The Node Hierarchy for H1 = A1|B1|C1|F1|H1


We can achieve this Scenario using the Recursive CTE in SQL Server as explained below:

SET ANSI_NULLS ON
GO
SET QUOTED_IDENTIFIER ON
GO

USE MyAnalyticsDB
GO

/* Check and Drop the table if it already exists: */
IF OBJECT_ID('[dbo].[tbl_Hierarchy]','U') IS NOT NULL
    BEGIN
        DROP  TABLE [dbo].[tbl_Hierarchy]
    END
ELSE
    BEGIN
       PRINT 'The target Object unable to Drop as it is Not Found'
    END

/* Create a Sample Hierarchy Table */
CREATE TABLE [dbo].[tbl_Hierarchy]
    (
        [RowID] [int] IDENTITY(1,1) NOT NULL,
        [ParentNodeId] [varchar](5) NULL,
        [ChildNodeId] [varchar](5) NOT NULL
    ) ON [PRIMARY]
    GO

/* Insert sample data into the Hierarchy table */
INSERT INTO [dbo].[tbl_Hierarchy]
SELECT NULL, 'A1' UNION ALL
SELECT 'A1', 'B1' UNION ALL
SELECT 'B1', 'C1' UNION ALL
SELECT 'B1', 'D1' UNION ALL
SELECT 'C1', 'E1' UNION ALL
SELECT 'C1', 'F1' UNION ALL
SELECT 'E1', 'G1' UNION ALL
SELECT 'F1', 'H1';

Select * From [dbo].[tbl_Hierarchy] ;

/* Create Recursive CTE to define the Hierarchy Node Levels Path */
;WITH CTE_Hierarchy
AS (
    SELECT
        RowID, ParentNodeId, ChildNodeId,
        CAST(ISNULL(ParentNodeId,'') + ChildNodeId AS VARCHAR(255)) [NodeLevelsPath]
    FROM tbl_Hierarchy
    WHERE ParentNodeId IS NULL

    UNION ALL

    SELECT
        t.RowID, t.ParentNodeId, t.ChildNodeId,
        CAST(c.[NodeLevelsPath] + '|' + t.ChildNodeId AS VARCHAR(255)) [NodeLevelsPath]
    FROM tbl_Hierarchy t
    INNER JOIN CTE_Hierarchy c ON c.ChildNodeId = t.ParentNodeId
    )

SELECT * FROM CTE_Hierarchy;


/* To Calculate the Child Node Level */
SELECT *,
        CONCAT('Level ',
            CAST(LEN(cte.[NodeLevelsPath])-LEN(REPLACE(cte.[NodeLevelsPath],'|',''))+1
                        AS VARCHAR(10) )
            )  AS "NodeLevel"

 FROM CTE_Hierarchy cte ;


----------------------------------------------------------------
Scenario 2:
In the following scenario, we consider the Numbers instead of Text for the Node levels. In this example, the base Parent node starts with 1 as a root Child ID and its Parent is NULL.

/* DROP TABLE [dbo].[tbl_Hierarchy] */
CREATE TABLE [dbo].[tbl_Hierarchy]
    (
        [RowID] [int] IDENTITY(1,1) NOT NULL,
        [ParentID] [varchar](5) NULL,
        [ChildID] [varchar](5) NOT NULL
    ) ON [PRIMARY]
    GO

/* TRUNCATE TABLE [dbo].[tbl_Hierarchy] */
INSERT INTO [dbo].[tbl_Hierarchy]
SELECT NULL, 1 UNION ALL
SELECT 1, 2 UNION ALL
SELECT 1, 3 UNION ALL
SELECT 2, 4 UNION ALL
SELECT 3, 5 UNION ALL
SELECT 2, 6

/* SELECT * FROM [dbo].[tbl_Hierarchy]; */


Now, we will generate the Parent-Child Node Levels Path using the Recursive CTE :

;WITH CTE_Hierarchy
 AS (
    -- Base case: Select the top-level parent
    SELECT 
        RowID, 
        ParentID, 
        ChildID, 
        CAST(ChildID AS VARCHAR(255)) AS NodeLevelsPath,
        ChildID AS RootChildID
    FROM [dbo].[tbl_Hierarchy]
    WHERE ParentID IS NULL  -- Start with the top parent
    UNION ALL
    -- Recursive case: Join child to parent and build the path
    SELECT 
        t.RowID, 
        t.ParentID, 
        t.ChildID, 
        CAST(c.NodeLevelsPath + '|' + t.ChildID AS VARCHAR(255)) AS NodeLevelsPath,
        c.RootChildID
    FROM [dbo].[tbl_Hierarchy] t
    INNER JOIN CTE_Hierarchy
        ON c.ChildID = t.ParentID 
)
-- Final select: Return the desired paths including the top-level parent
SELECT RowID, ParentID, ChildID, NodeLevelsPath
FROM CTE_Hierarchy
ORDER BY NodeLevelsPath;

--Result:

----------------------------------------------------------------
Scenario 3:
In the below scenario, the root Parent node starts with 1 as a base, and Its Parent information is not available.

/* DROP TABLE [dbo].[tbl_Hierarchy] */
CREATE TABLE [dbo].[tbl_Hierarchy]
    (
        [RowID] [int] IDENTITY(1,1) NOT NULL,
        [ParentID] [varchar](5) NULL,
        [ChildID] [varchar](5) NOT NULL
    ) ON [PRIMARY]
    GO

/* TRUNCATE TABLE [dbo].[tbl_Hierarchy] */
INSERT INTO [dbo].[tbl_Hierarchy]
SELECT 1, 2 UNION ALL
SELECT 1, 3 UNION ALL
SELECT 2, 4 UNION ALL
SELECT 3, 5 UNION ALL
SELECT 2, 6

/* SELECT * FROM [dbo].[tbl_Hierarchy]; */


Now, we will generate the Parent-Child Node Levels Path using the Recursive CTE :
;WITH CTE_Hierarchy 
 AS (
    -- Base case: Select initial parent-child relationship with top-level parents
    SELECT 
        RowID, ParentID, ChildID, 
        CAST(ParentID + '|' + ChildID AS VARCHAR(255)) AS NodeLevelsPath,
        ParentID AS RootParentID
    FROM [dbo].[tbl_Hierarchy]
    WHERE ParentID = '1'  -- Start with the top parent
    UNION ALL
    -- Recursive case: Join child to parent and build the path
    SELECT 
        t.RowID, t.ParentID, t.ChildID, 
        CAST(c.NodeLevelsPath + '|' + t.ChildID AS VARCHAR(255)) AS NodeLevelsPath,
        c.RootParentID
    FROM [dbo].[tbl_Hierarchy] t
    INNER JOIN CTE_Hierarchy
        ON c.ChildID = t.ParentID 
)
-- Final select: Return only the desired paths
SELECT RowID, ParentID, ChildID, NodeLevelsPath
FROM CTE_Hierarchy
WHERE RootParentID = '1'
ORDER BY NodeLevelsPath;

--Result:


--------------------------------------------------------------------------------------------------------
Thanks, TAMATAM ; Business Intelligence & Analytics Professional
--------------------------------------------------------------------------------------------------------

Tuesday, April 4, 2023

How to Generate Dynamic Range of Sequence Numbers in SQL Server

How to Generate specific Range of Sequence Numbers in SQL Server
Scenario:
Suppose we would like to generate the Sequence of numbers between the specified Start and End ranges. ( Eg: Say Numbers between 5 and 15 )

We can achieve this by using the Recursive CTE feature of SQL, as discussed below.

CTE (common table expression):
The CTE (common table expression) is an SQL feature will be defined using WITH Clause, that returns a temporary data set which can be used by another query. The scope of CTE is limited to the Current query.

Syntax:
WITH cte_name
AS
(
   cte_query_definition
)
SELECT * FROM cte_name;

Recursive CTE:
Since it’s a temporary result, will not stored anywhere, but it still can be referenced like you would reference any other table.
A Recursive CTE references itself. It returns the result subset, then it repeatedly (recursively) references itself, and stops when it returns all the results.

Syntax:
WITH cte_name
AS
(
    cte_query_definition (or) initial query  -- Anchor member
    UNION ALL
    recursive_query with condition     -- Recursive member
)
SELECT * FROM cte_name

Example :
Generating the Numbers between 5 to 15 using the Recursive CTE method.

/* Variable declaration method:
DECLARE @StartNum INT , @EndNum INT ;
Select @StartNum=1, @EndNum=10000
*/

DECLARE @StartNum INT=5
DECLARE @EndNum INT=15
;
WITH Seq_RecCTE
AS 
(
    SELECT @StartNum AS Num
    UNION ALL
    SELECT sn.Num+1 FROM Seq_RecCTE  sn
WHERE sn.Num+1<=@EndNum
)

SELECT * FROM Seq_RecCTE
Option (MaxRecursion 32767) ;

/* To insert the result to a New Table :
SELECT * INTO tbl_SeqNumbers
FROM Seq_RecCTE
Option (MaxRecursion 32767) ;
*/

Result:
--------------------------------------------------------------------------------------------------------
Thanks, TAMATAM ; Business Intelligence & Analytics Professional
--------------------------------------------------------------------------------------------------------

Monday, March 20, 2023

How to find Average for each Category for the Selected Period in SQL Server

How to find Average Billing amount for each Category for the Selected Years
Scenario:
Suppose we have a sample billings data table "tbl_billings", with the fields Cust_Id, Cust_Name,
Billing_ID, Billing_Date, Billing_Ammount.

Select * From [dbo].[tbl_billings]


Now we need to calculate the Average Billing Amount for each Customer for the period between 2019 to 2021, with the following assumptions:

-- We need to consider the Billing amount as Zero(0) for the Year where there is no billing.
-- We need to consider the Billing count as One(1) for the Year where there is no billing (=0).

Now lets implement the above Scenario using the below Queries.

In the following Query, we can calculate the Sum of Billing Amounts and Count of Billings for the Periods 2019, 2020, 2021 :

WITH cte_Billings  AS
(
Select Cust_ID , Cust_Name,
SUM( Case When DATEPART(Year,[Billing_Date]) = 2019 Then [Billing_Amount] Else 0 End) As  'Amt_2019',
SUM( Case When DATEPART(Year,[Billing_Date]) = 2020 Then [Billing_Amount] Else 0 End) As 'Amt_2020',
SUM( Case When DATEPART(Year,[Billing_Date]) = 2021 Then [Billing_Amount] Else 0 End) As 'Amt_2021',

COUNT( Case When DATEPART(Year,[Billing_Date]) = 2019 Then [Billing_Amount] Else null End) As  'Cnt_2019',
COUNT( Case When DATEPART(Year,[Billing_Date]) = 2020 Then [Billing_Amount] Else null End) As 'Cnt_2020',
COUNT( Case When DATEPART(Year,[Billing_Date]) = 2021 Then [Billing_Amount] Else null End) As 'Cnt_2021'

From [dbo].[tbl_billings]
Group By Cust_ID , Cust_Name
)
Select *  From cte_Billings

Result:


As per our Scenario, when there is no Billing Amount(Eg: Amt_2019 = 0), we have to consider the respective Year Billing Amount as 0 and the Count as 1.

In this way, we adjust the final Output Query, the Select part of CTE as per below:

WITH cte_Billings  AS
(
Select Cust_ID , Cust_Name,
SUM( Case When DATEPART(Year,[Billing_Date]) = 2019 Then [Billing_Amount] Else 0 End) As  'Amt_2019',
SUM( Case When DATEPART(Year,[Billing_Date]) = 2020 Then [Billing_Amount] Else 0 End) As 'Amt_2020',
SUM( Case When DATEPART(Year,[Billing_Date]) = 2021 Then [Billing_Amount] Else 0 End) As 'Amt_2021',

COUNT( Case When DATEPART(Year,[Billing_Date]) = 2019 Then [Billing_Amount] Else null End) As  'Cnt_2019',
COUNT( Case When DATEPART(Year,[Billing_Date]) = 2020 Then [Billing_Amount] Else null End) As 'Cnt_2020',
COUNT( Case When DATEPART(Year,[Billing_Date]) = 2021 Then [Billing_Amount] Else null End) As 'Cnt_2021'

From [dbo].[tbl_billings]
Group By Cust_ID , Cust_Name
)

Select Cust_ID , Cust_Name,
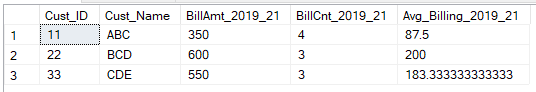
(Amt_2019+Amt_2020+Amt_2021) As BillAmt_2019_21,

((Case When Cnt_2019 = 0 Then 1 Else Cnt_2019 End)
+(Case When Cnt_2020 = 0 Then 1 Else Cnt_2020 End)+
(Case When Cnt_2021= 0 Then 1 Else Cnt_2021 End )) As BillCnt_2019_21,

(Amt_2019+Amt_2020+Amt_2021)
((Case When Cnt_2019 = 0 Then 1 Else Cnt_2019 End)
+(Case When Cnt_2020 = 0 Then 1 Else Cnt_2020 End)+
(Case When Cnt_2021= 0 Then 1 Else Cnt_2021 End )) As Avg_Billing_2019_21
From cte_Billings

Final Result :

--------------------------------------------------------------------------------------------------------
Thanks, TAMATAM ; Business Intelligence & Analytics Professional
--------------------------------------------------------------------------------------------------------

Featured Post from this Blog

How to compare Current Snapshot Data with Previous Snapshot in Power BI

How to Dynamically compare two Snapshots Data in Power BI Scenario: Suppose we have a sample Sales data, which is stored with Monthly Snapsh...

Popular Posts from this Blog